AI Governance
What Google's Nested Learning Paper Means for Mid-Market Teams.
By John Utley
Published
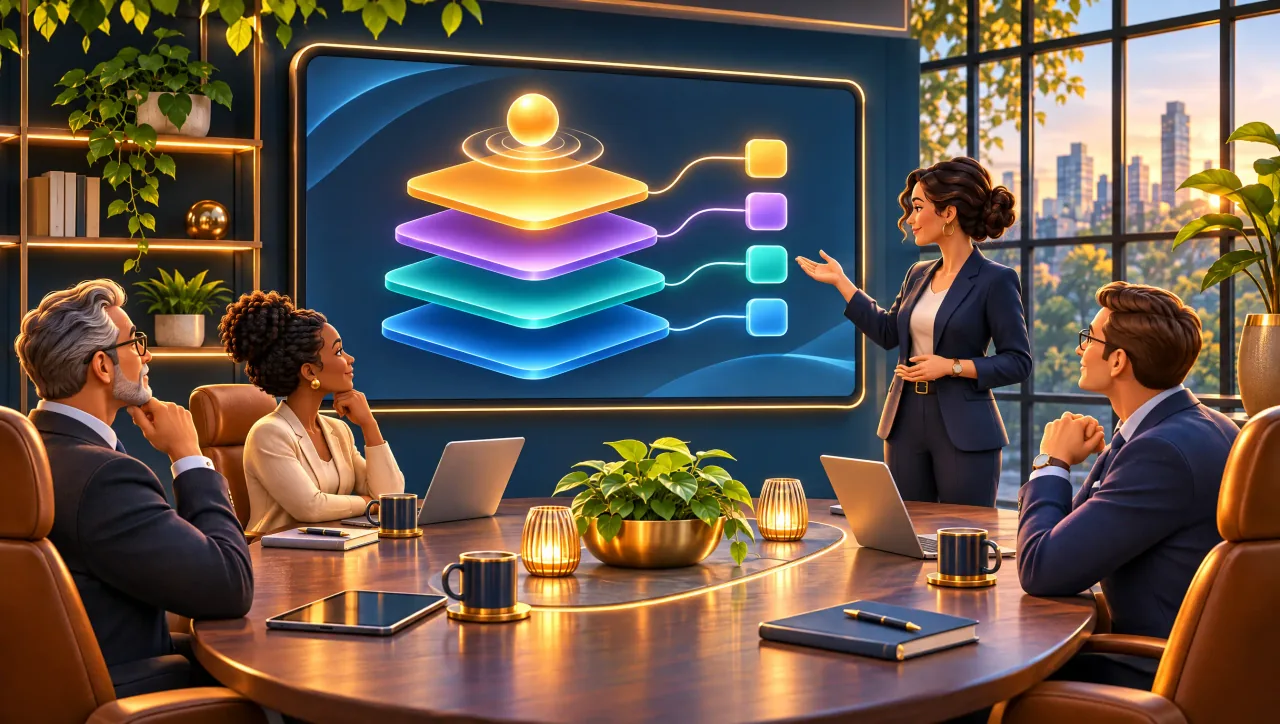
Google's Nested Learning paper, presented at NeurIPS 2025, argues that a deep learning model is really a stack of learning problems running at different speeds, and that the model's structure and its training rule are the same kind of thing at different levels. From that idea the authors describe a Continuum Memory System and Hope, a self-modifying proof-of-concept model.
This is research, not a product. Hope was tested at 760 million and 1.3 billion parameters. Clients cannot buy or deploy it. Sophizo does not sell Nested Learning or the Hope model. We mention the paper because operators will see the headlines and should know what is, and is not, available today.
The useful translation is about speed and ownership. Some memories should update quickly. Some should barely move. If a system can change after launch, a one-time validation is not enough. You will need to version both the model and the memory, log which version made each call, and define what triggers a re-validation. Those practices map to NIST AI RMF Measure and Manage, and to ISO 42001 monitoring and continual improvement.
Mid-market teams do not need to wait for a new model to act on that. Design fast, medium, and slow memory on the tools you already have. Promote a lesson into durable policy only after a person reviews it. Give that policy a named owner and a rollback path.
What not to do: treat the paper as a buying guide, drop unreviewed chat logs into a long-term store, or assume a policy binder written for a frozen model will still be enough next year.
Sources: Google Research, Introducing Nested Learning. Behrouz et al., Nested Learning: The Illusion of Deep Learning Architectures, arXiv 2512.24695.